6 min read
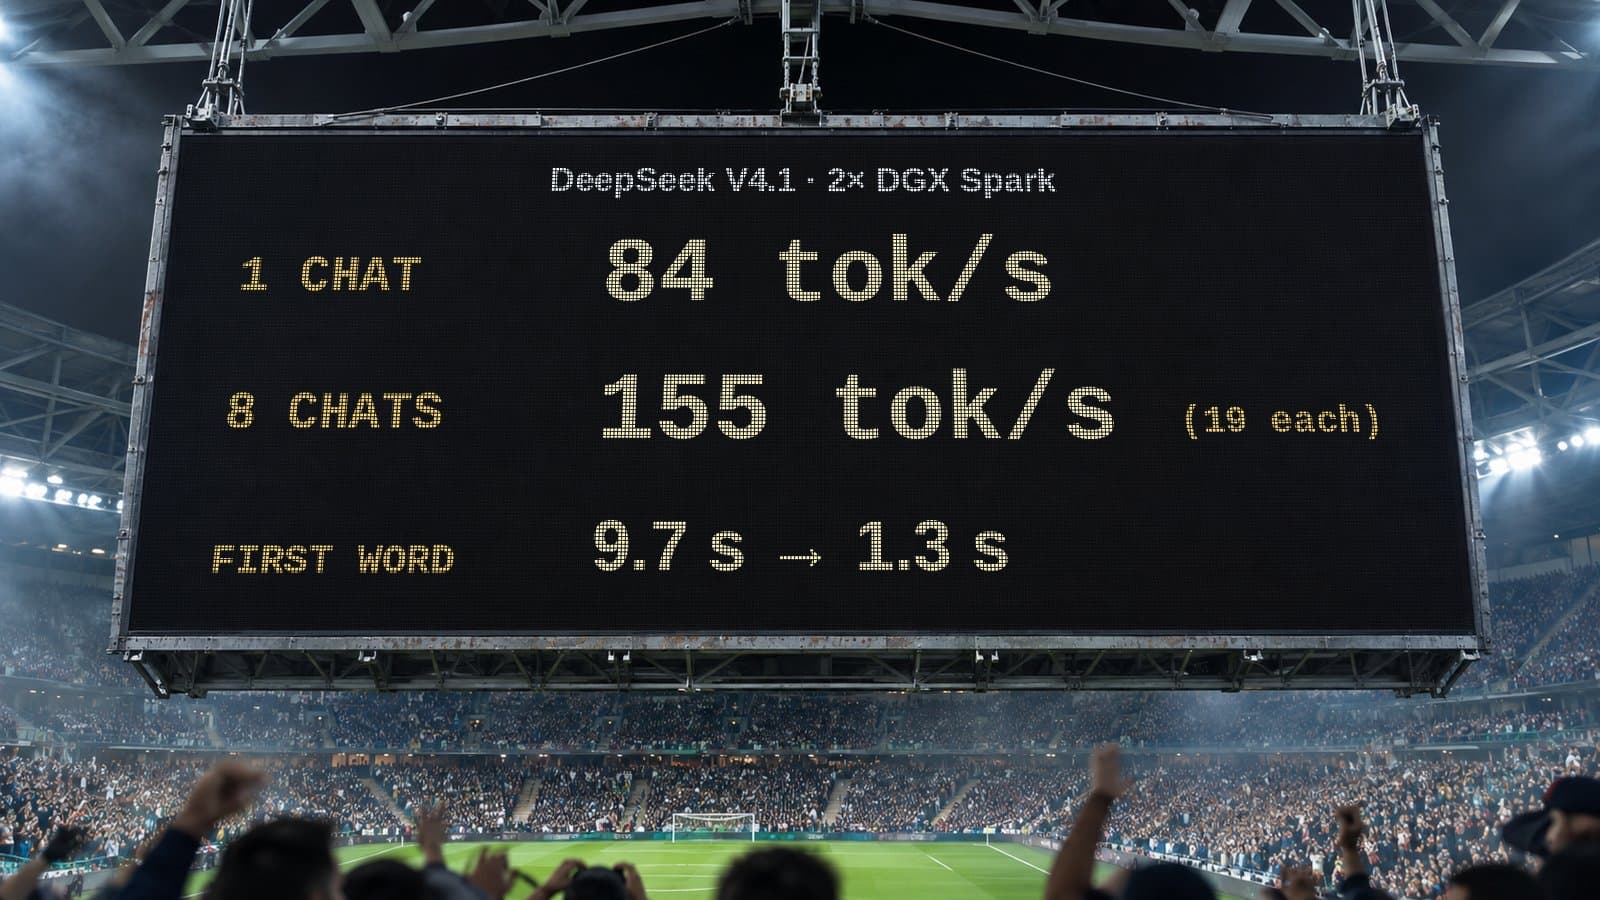
How many people can share one local AI setup? My DeepSeek numbers
One chat on two DGX Sparks gets 84 tok/s. Eight at once share 155 tok/s. What that means when you plan local AI for a whole team, not just one person.
Articles about ai-infrastructure.
6 min read
One chat on two DGX Sparks gets 84 tok/s. Eight at once share 155 tok/s. What that means when you plan local AI for a whole team, not just one person.
5 min read
Cloud AI prices and hardware costs are likely to rise. How I match models to tasks and move work to local AI so my business isn't caught out.
5 min read
My local DeepSeek setup got 6.3s replies instead of 26.9s with 78% fewer tokens on computation tasks, and no gain on standard benchmarks. Here's why.
5 min read
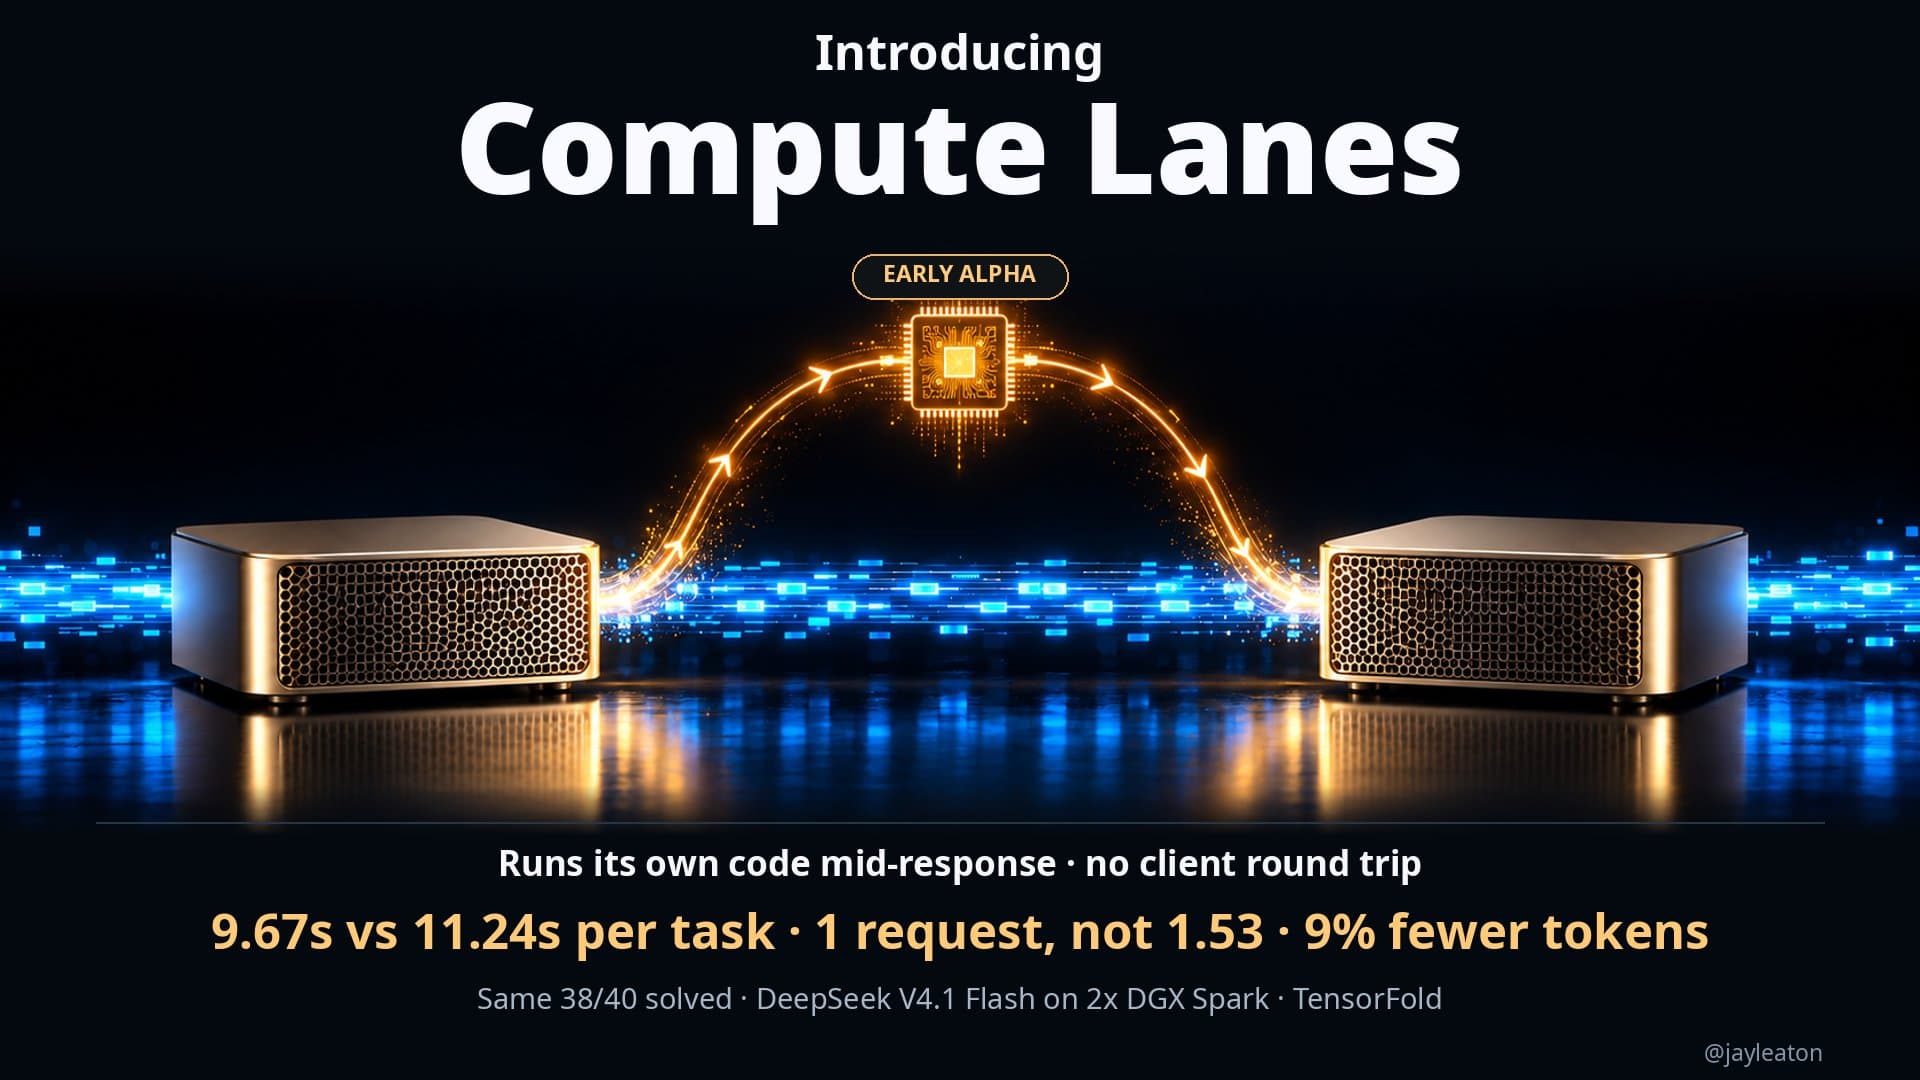
I gave my local DeepSeek setup a way to run code mid-response. Same 38 of 40 coding tests solved, 16% faster overall, with fewer requests and tokens.
6 min read
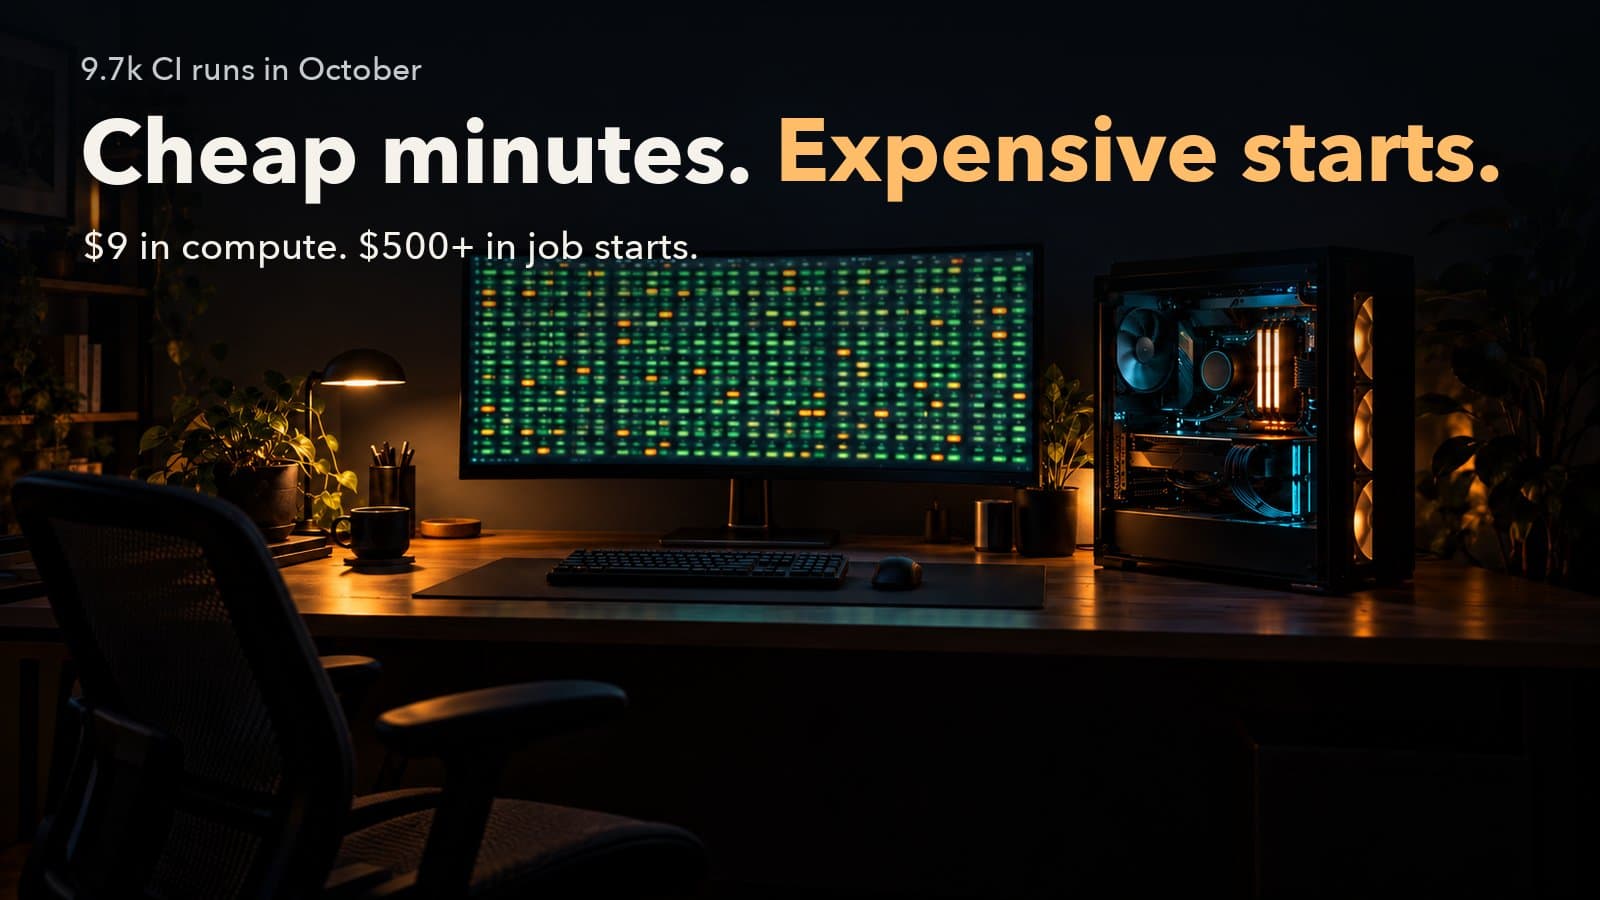
Our app ran about 9.7k CI workflows in October. Compute would cost around $9 on one host, but plan limits on job starts would push it past $500.
5 min read
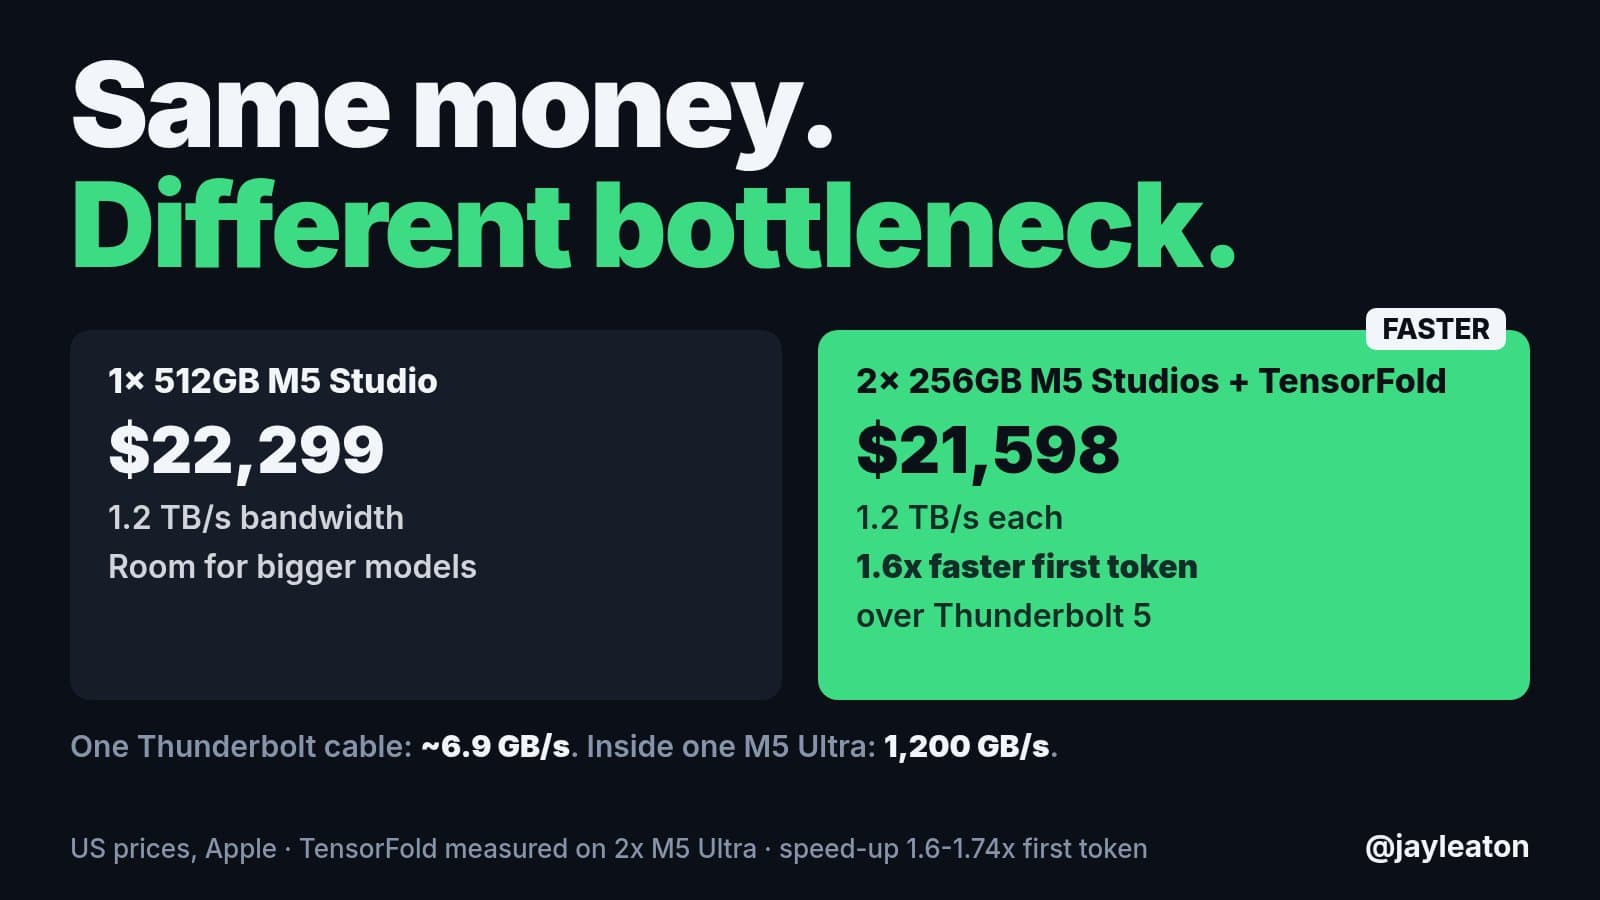
For the same money, two smaller machines beat one big one for local AI: faster first token, double the compute, no single point of blocking, better resale.